Hosted error tracking

4,000 crashes.
One issue.

BugCatch catches unhandled exceptions across your web, Node, Java, and React Native apps, fingerprints each one, and collapses the duplicates. You get a single issue with the stack trace and the clicks that led to it - not four thousand identical emails.

Free to start · No credit card · Your first error in under five minutes

  • SDKs
  • JavaScript / TypeScript
  • Node.js
  • React Native & Expo
  • Java 21+
  • Zero runtime dependencies. ~15 KB.

What it is

An error tracker for teams who want the signal without the enterprise contract.

Install the SDK, paste a DSN, ship. From then on every uncaught exception and rejected promise arrives with a resolved stack trace, the breadcrumb trail that preceded it, the user it happened to, and the release it shipped in.

BugCatch also watches the things that break without throwing: endpoints that got slow, queries that got slower, heap that keeps climbing, and URLs that stopped responding.

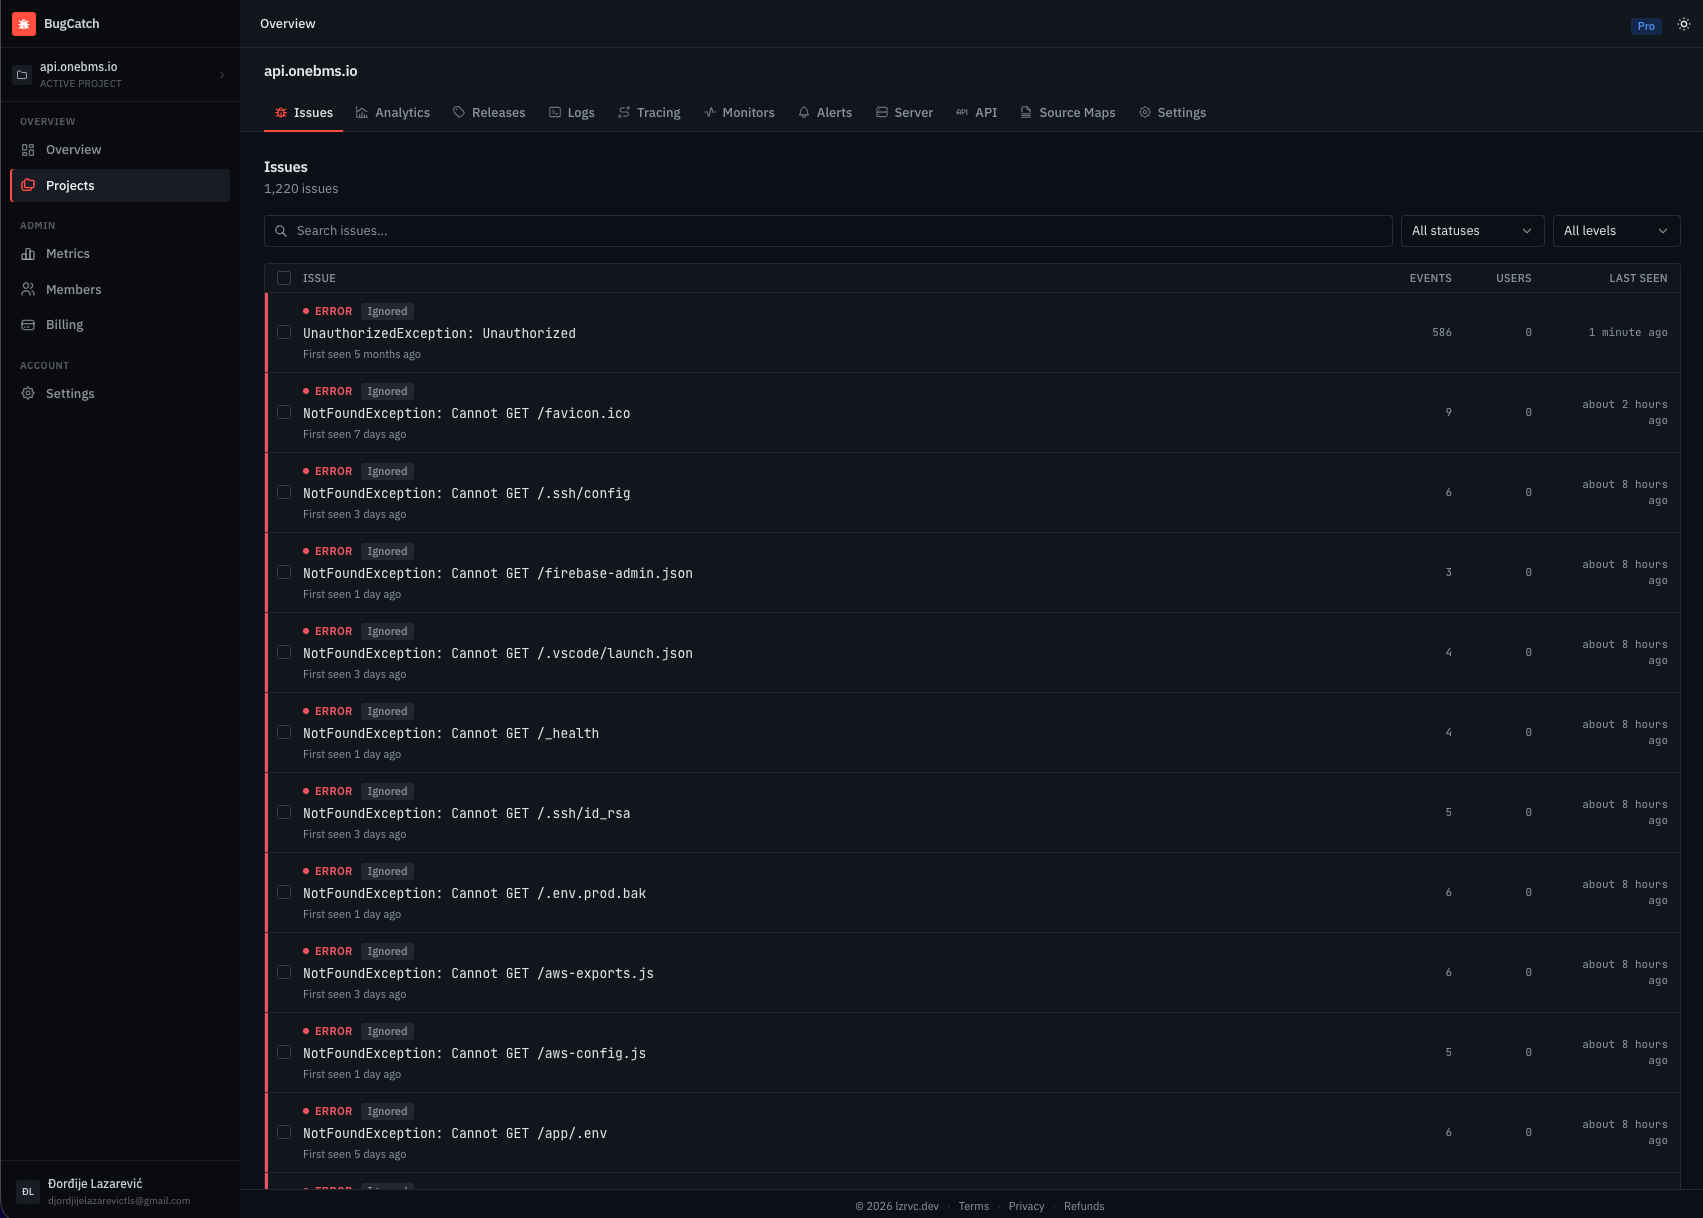
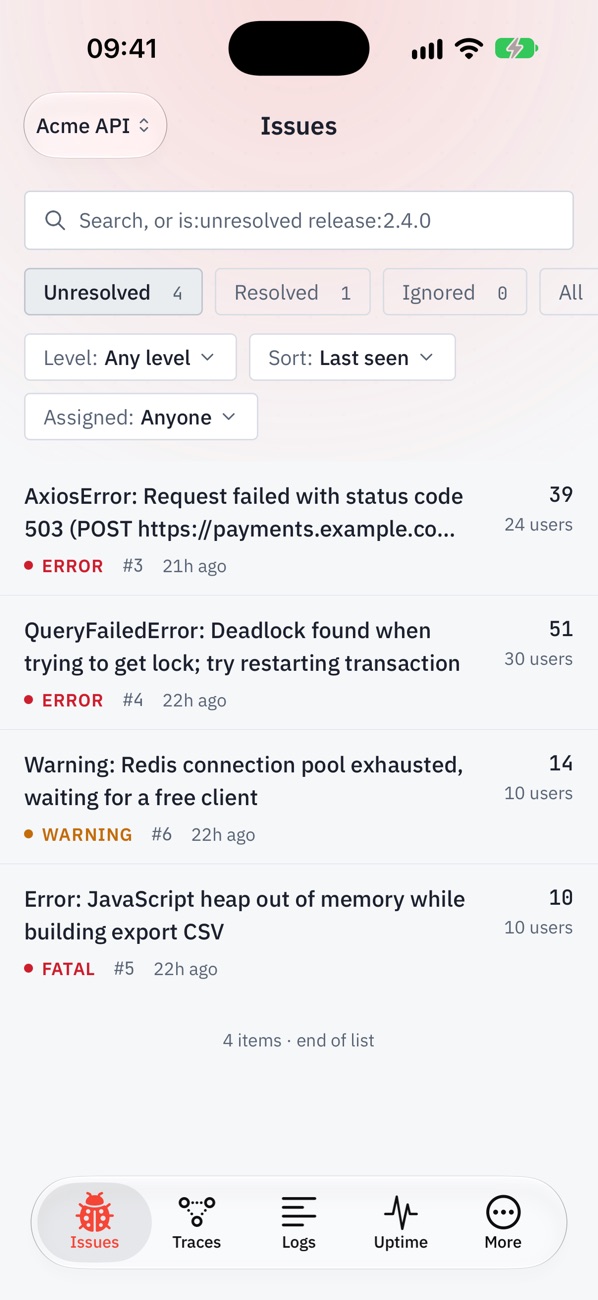
BugCatch issues list showing grouped errors and warnings with event counts, affected users, and last-seen times.
The issue list after fingerprinting. One row per distinct crash.

Event pipeline

What happens between the crash and your inbox

Four steps. Your app never waits for any of them.

  1. 01

    The SDK catches it

    Global handlers pick up uncaught errors and unhandled rejections. The SDK parses the stack, attaches the last 100 breadcrumbs - clicks, navigation, console warnings - plus the user, release, and environment you set.

  2. 02

    Ingest answers immediately

    The SDK key is checked against a Redis cache and the event goes onto a queue. Your app gets its response back right away - no blocking call, no latency added to the request that already failed.

  3. 03

    The worker fingerprints and groups

    A SHA-256 of the error type, message, and location becomes the fingerprint. A new fingerprint opens an issue. A known one increments its counters and adds the user to a set. Same crash, same row.

  4. 04

    You hear about it once

    New issues and regressions trigger an email or a webhook. Cooldowns hold the line at one notification per issue per four hours, so a crash loop stays a single message.

Capabilities

Grouped by where you actually meet them

In your code

What the SDK does once it's initialised.

  • Automatic capture

    Uncaught errors and unhandled promise rejections, with no per-call wiring. Add captureException and captureMessage where you want detail.

  • Breadcrumb trail

    Clicks, navigation, and console warnings from the 100 events before the crash, so you can reproduce it instead of guessing.

  • User context and tags

    Attach the signed-in user after login, tag by plan or region, and filter issues by any of it later.

  • Only real bugs

    Errors carrying a 4xx status - a 404 from a scanner probing paths, a 400 from bad input - are skipped. They're the caller's mistake, not a bug in your code. Turn them back on with captureClientErrors.

  • beforeSend

    A hook that runs before anything leaves the process. Scrub fields, drop noisy error classes, or return false to discard the event.

  • Services and background jobs

    Give each service a serviceName and outgoing requests carry a W3C traceparent, so one request through your API, worker and payment service is one trace. Wrap a BullMQ worker and every job shows up with its runs, failures, retries and queue wait.

  • Customer accounts

    setAccount({ id, name }) tags errors and requests with the customer they belong to - see which client is having a bad day, and how much of your volume each one is.

  • CPU profiling

    profiling: true records 10 seconds of CPU every minute through Node's built-in inspector and merges them into one flame graph. No native addon. Pro and above.

  • A CLI for your pipeline

    npx bugcatch login approves a machine in the browser. Register releases, mark deploys and upload source maps from CI with one token.

On the dashboard

What you open when something looks wrong.

  • Readable stack traces

    Upload a source map per release and minified frames resolve to the original file, line, and column.

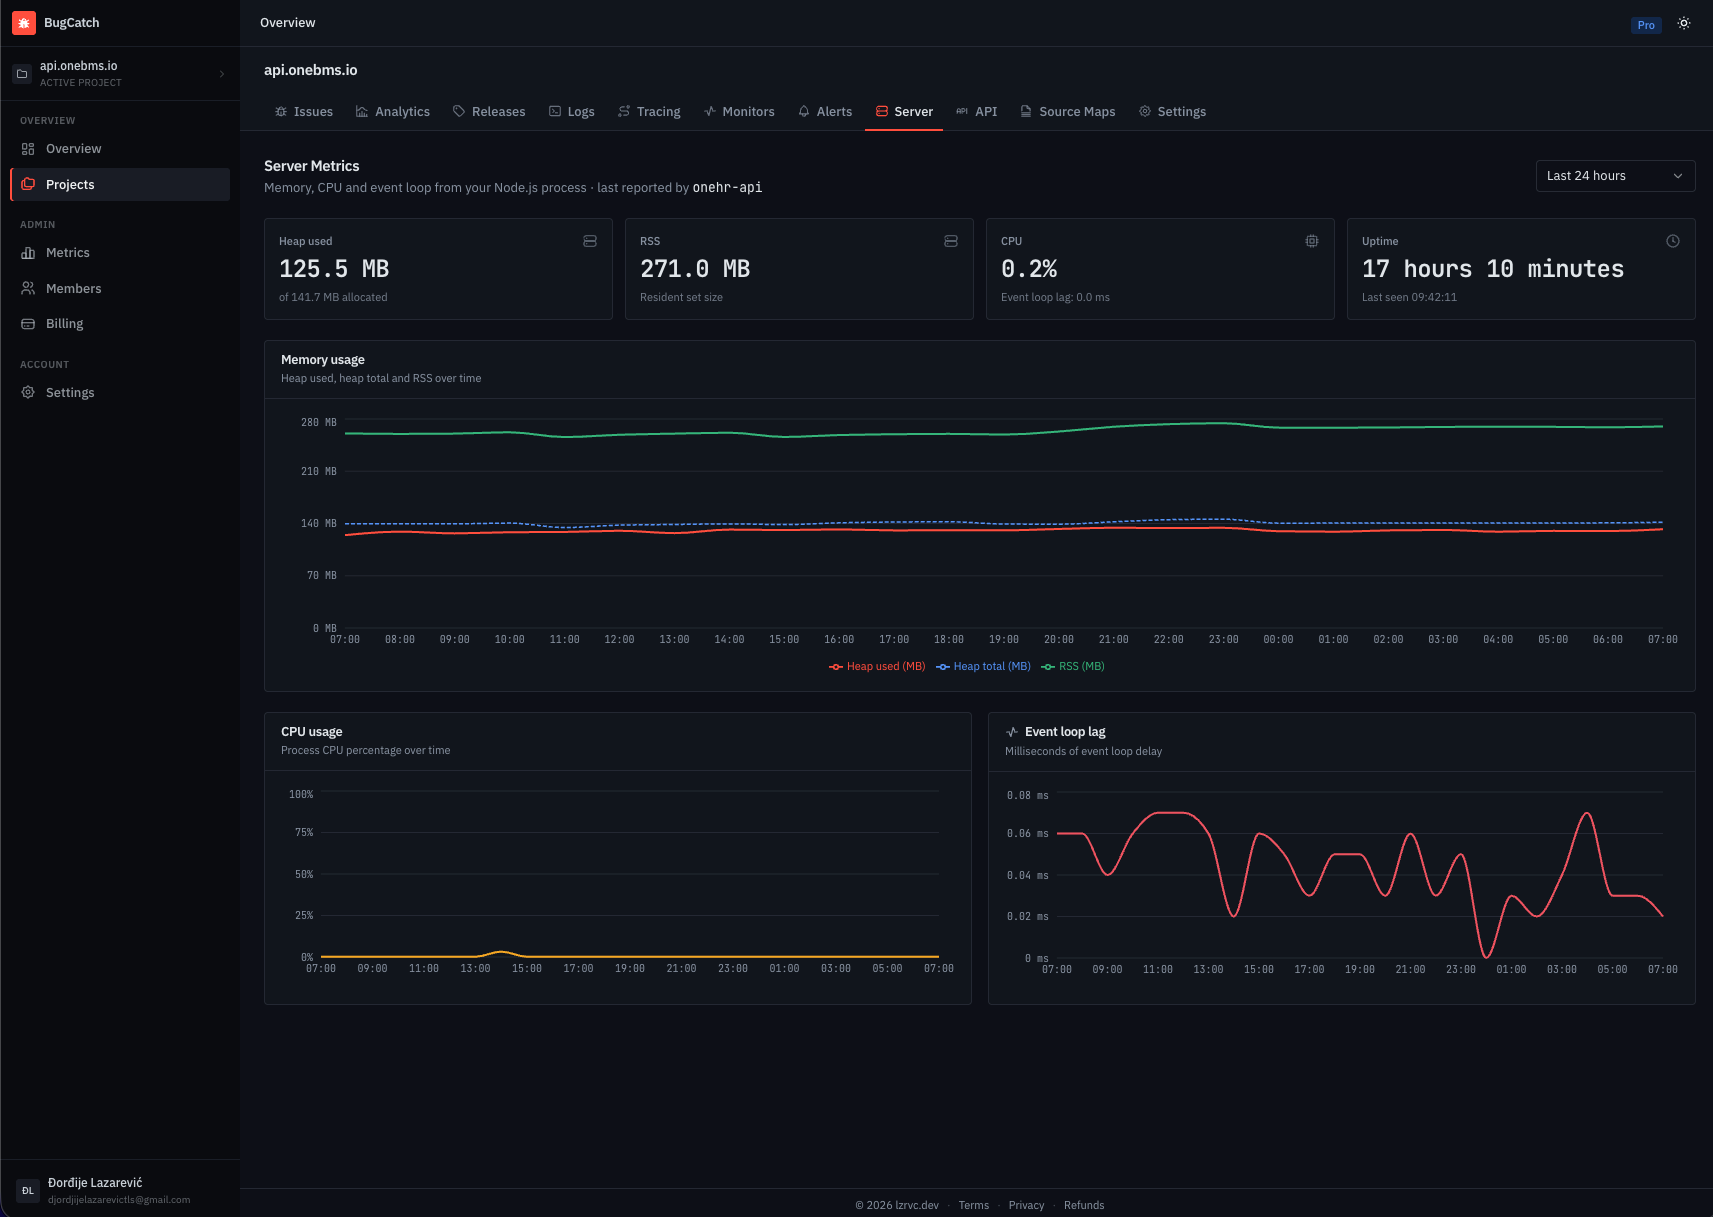
  • Server metrics

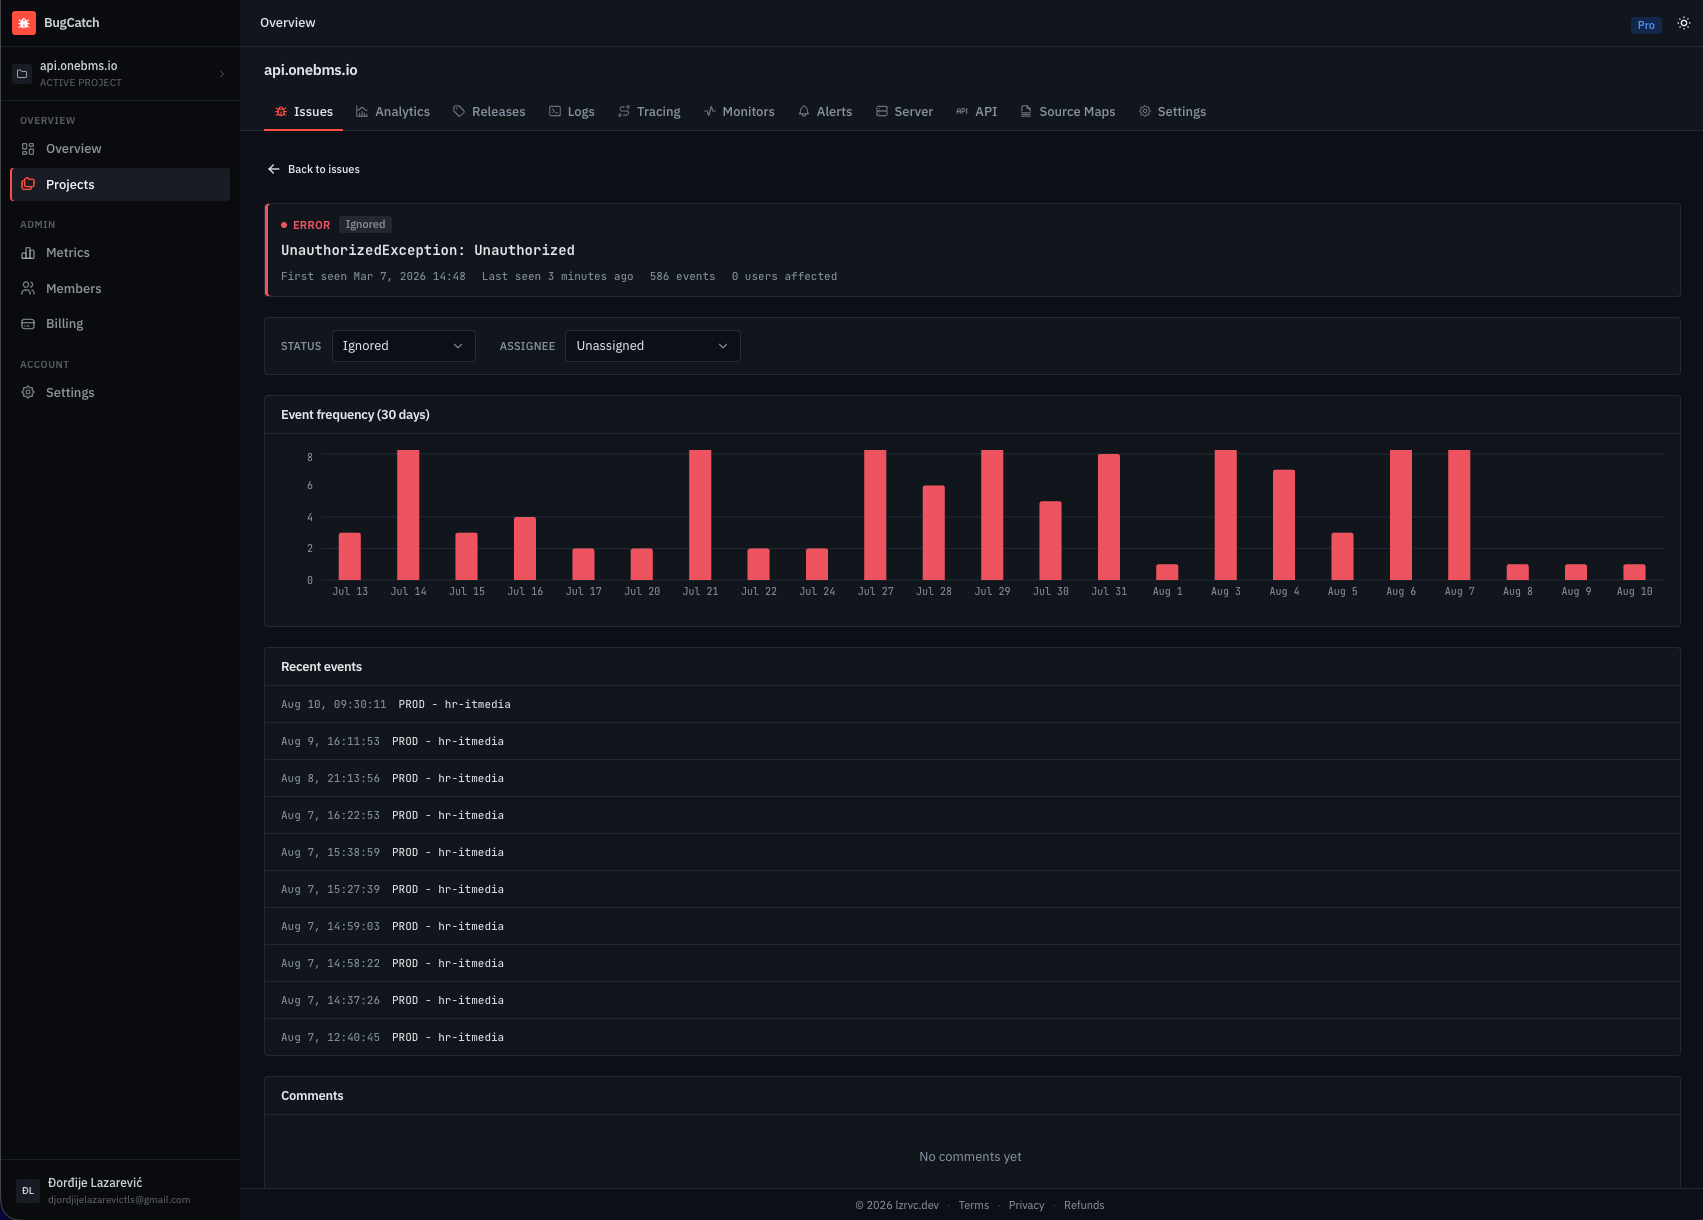
    Heap, CPU, and event loop lag reported per instance, so you can tell one struggling pod from a fleet-wide problem.

  • API and query timing

    Slow routes and slow database queries logged against their own thresholds, separate from your error stream.

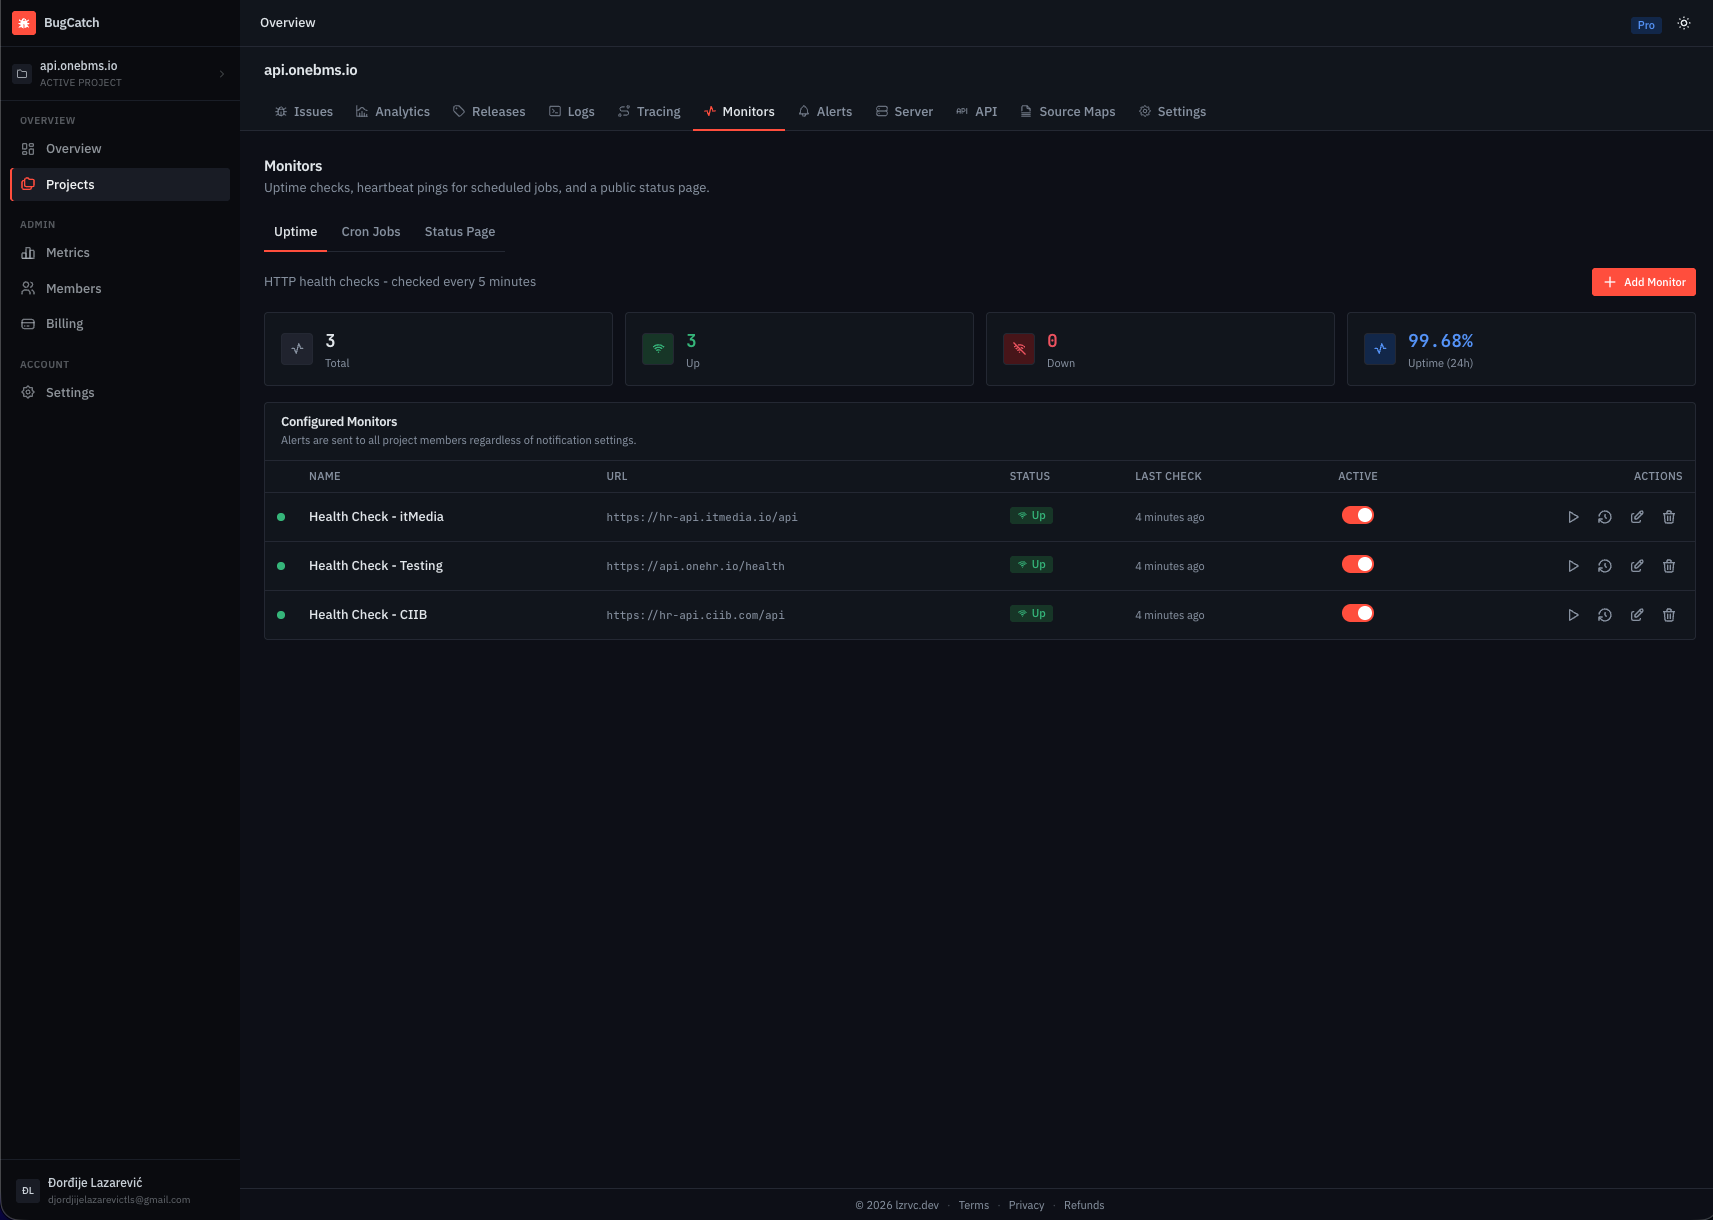
  • Uptime and cron monitors

    HTTP checks every five minutes for URLs, plus heartbeat pings for background jobs - three retries before a URL is called down, a missed ping before a job is.

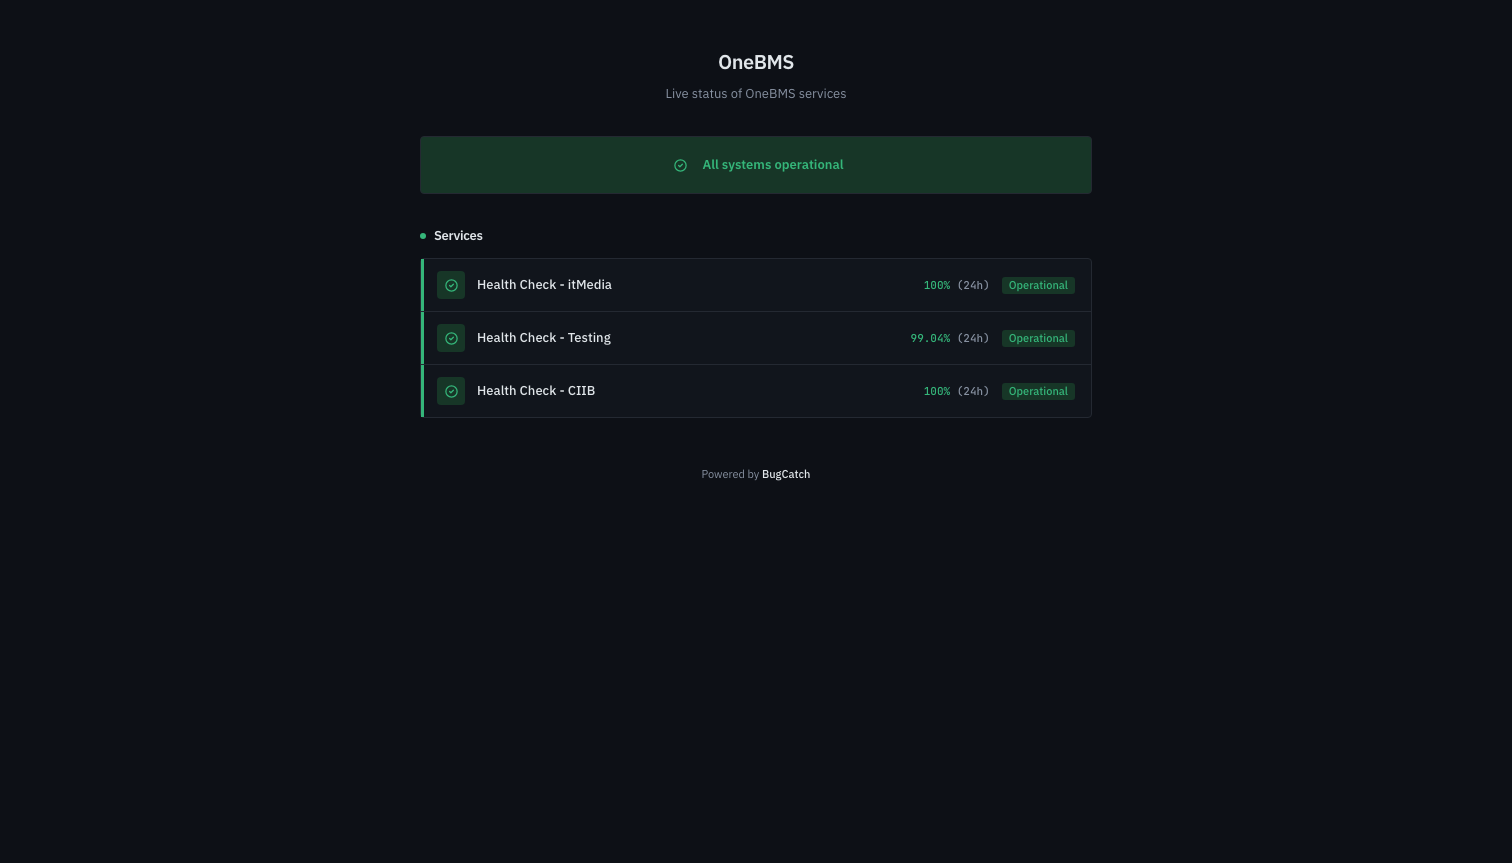
  • Public status pages

    A page at your own slug showing the monitors you choose and any incident you post, for the people who'd otherwise be asking you in a DM.

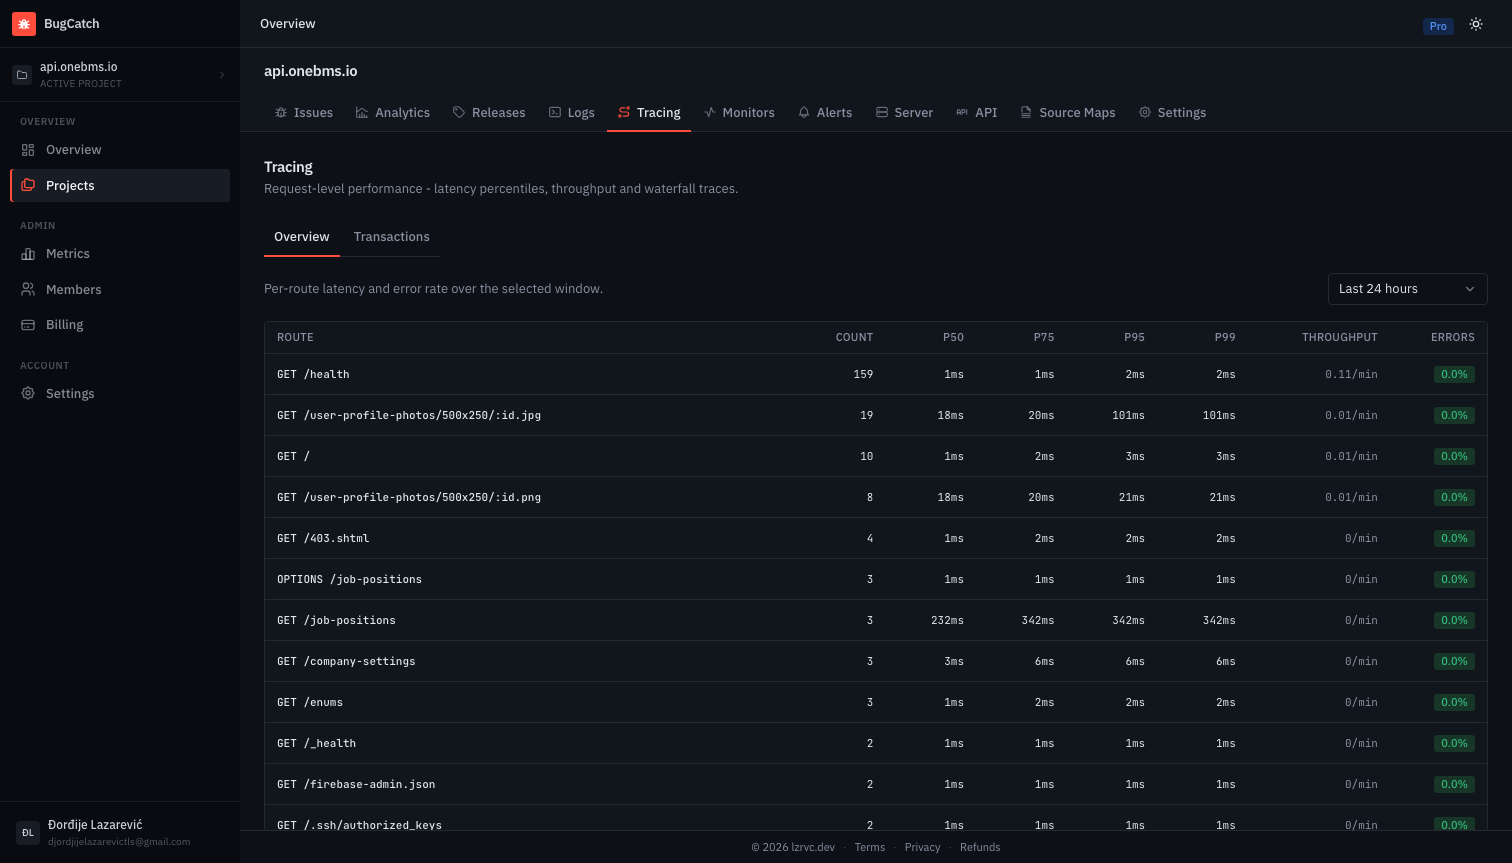
  • Distributed tracing and the service map

    See which request, and which part of it, was slow. Traces that cross services draw a map of who calls whom, with volume, latency and failure rate on every edge. Pro and above.

  • Custom dashboards

    Arrange the charts you already have into a grid that opens the way you actually work. Pro and above.

  • N+1 detection

    The same query fired again and again inside one request becomes a performance issue, with the repeated SQL attached.

  • Session replay

    Watch what the user did before the error. Inputs are always masked, and nothing is recorded until you turn it on. Pro and above.

  • Web Vitals and crash-free sessions

    LCP, INP and CLS from real visitors, per route, and the share of sessions and users that never crashed. Pro and above.

  • SLOs and release impact

    Set an availability or latency target and watch the error budget. Every release is compared with the hours before it went out, route by route. SLOs are Pro and above.

  • Users and accounts

    Every user and every customer account on one page each - their errors, slow requests, sessions and replays.

  • Priority, due dates and a prompt for your agent

    Triage with a priority and a due date, then copy a ready-made brief - stack, source, request, breadcrumbs - for Claude Code or Cursor, or ask Claude for the likely cause and a fix.

  • Spend controls

    Sample traces, drop noisy transactions and chatty log levels before they count toward your volume, and keep spans only as long as you need them. Failed requests and error logs are always kept.

  • MCP server

    Connect Claude Code or any MCP client to your projects and ask about issues, traces, logs and releases in plain language. Read-only. Pro and above.

  • Team and triage

    Invite members per project or share projects with a whole team, comment on issues, merge duplicates the fingerprint missed, and bulk resolve or ignore once you've shipped the fix.

  • Single sign-on

    Sign your team in through your identity provider - Google Workspace, Okta, Entra ID or any OIDC provider - on domains you've proven with a DNS record. Business.

  • Retention you control

    Old events age out on a schedule you set, so the dashboard stays fast and storage stays bounded.

In your inbox and on your phone

What reaches you when you're not looking.

  • New issues and regressions

    Email the first time a fingerprint appears, and again if something you resolved comes back.

  • The mobile app

    Push alerts per project - everything, critical only, or off - with quiet hours on each device. Tap one and it opens on the issue; links to the dashboard open in the app too.

  • Webhooks

    The same events posted to your endpoint, on the same four-hour cooldown, for Slack or anything else you route to.

  • Threshold alerts

    Memory, CPU, slow endpoints, and downed monitors, each on an independent cooldown so one bad afternoon doesn't become fifty emails.

  • Anomaly alerts

    Error volume, route latency and traffic are compared with their own last seven days. A real departure alerts you; an ordinary busy hour doesn't.

  • Mute schedules

    Silence alerts for a maintenance window, or every weekend night, in your own time zone.

  • Weekly reports

    A project digest every Friday at noon and an uptime summary every Monday at two, both to every member.

The mobile app

The same data, in your pocket

Push alerts that open on the issue, plus issues, traces, logs, and uptime for every project. Links to the dashboard open in the app.

BugCatch mobile app issues list with level, event counts, and affected users.
Issues, filtered and sorted.
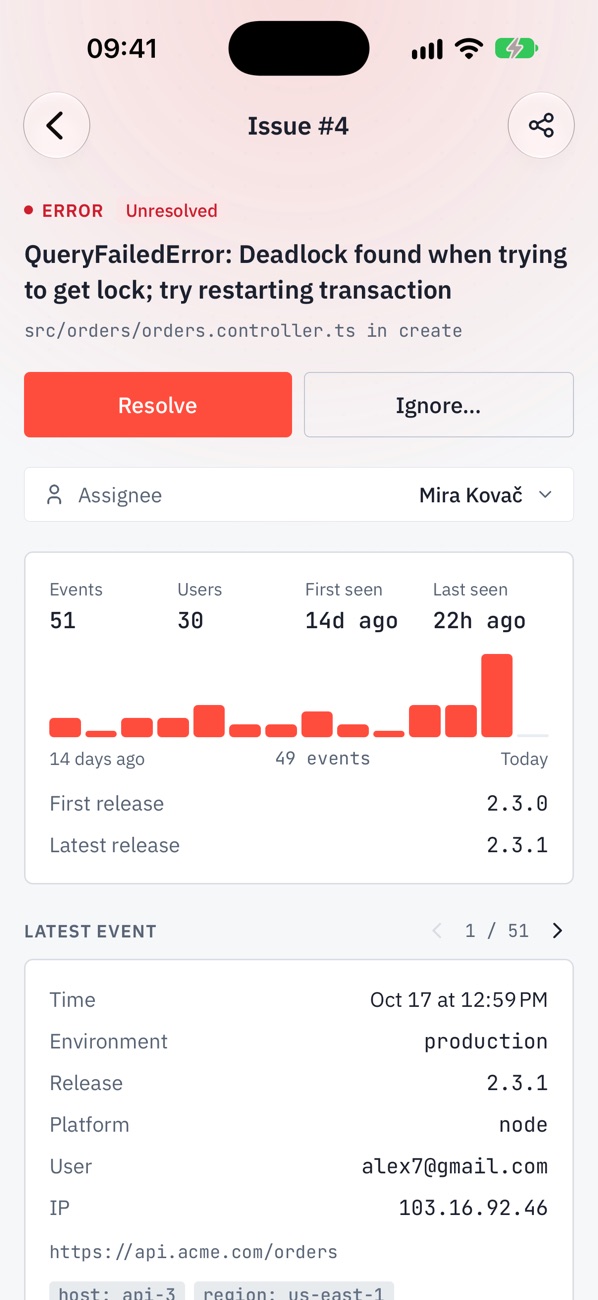
BugCatch mobile app issue detail with resolve and ignore buttons, assignee, and event chart.
Resolve, ignore, or assign.
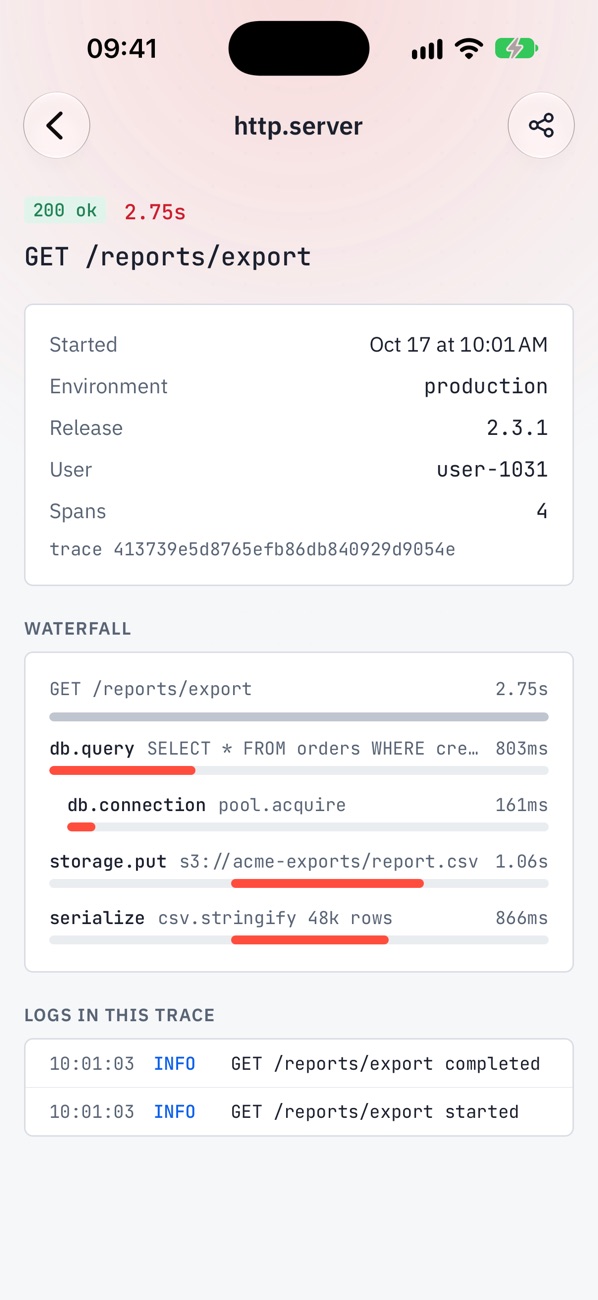
BugCatch mobile app trace waterfall for a slow request, with its logs below.
The slow span, and its logs.
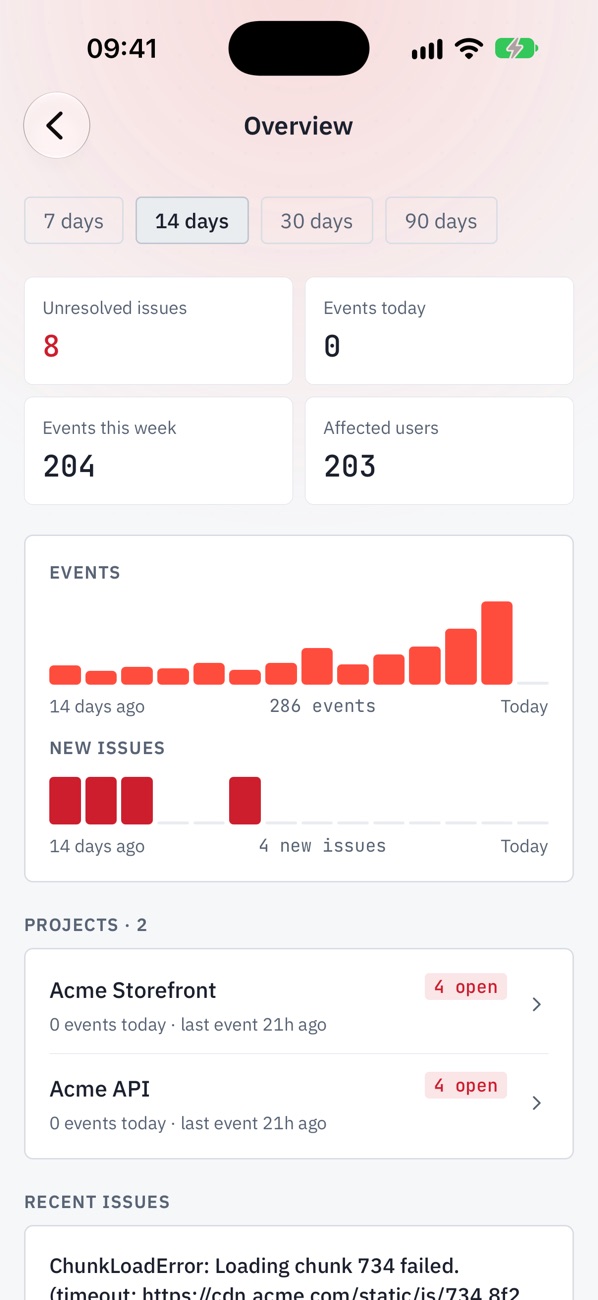
BugCatch mobile app overview with unresolved issues, events, and new issues across projects.
Every project at a glance.

Integration

One init call and you're reporting

Create a project, copy its DSN from the dashboard, and pass it to init. Everything after that is automatic.

npm install bugcatch-sdk
src/main.tsx
import BugCatch from 'bugcatch-sdk';

BugCatch.init({
  dsn: import.meta.env.VITE_BUGCATCH_DSN,
  release: import.meta.env.VITE_APP_VERSION,
  environment: import.meta.env.MODE,
});

// Identify the user once they sign in.
BugCatch.setUser({ id: user.id, email: user.email });
BugCatch.setTag('plan', 'pro');

Alerting

Quiet by design

Most error tools fail at the second crash, not the first. BugCatch puts every notification behind a cooldown keyed to the issue, so a loop that fires ten thousand times still costs you one message.

Each alert class gets its own timer. A memory warning doesn't suppress a downed monitor, and a slow endpoint doesn't bury a new exception.

Scanners get the same treatment. Requests for routes that don't exist become one issue per HTTP method, not one per probed path, and an IP that opens ten new issues in ten seconds opens none for the next hour.

New issue or regression
Immediatethen one per 4 hours
Spike detected
Immediateone per issue per 24 hours
Phone push
Immediateat most 5 per project per 10 min
Scanner burst
Muted10 new issues from one IP in 10 s
Webhook delivery
Immediate4-hour cooldown per event type
Memory, CPU
On threshold15-min cooldown each
Uptime & cron checks
Every 5 mindown after 3 retries, or a missed ping
Project digest
Friday 12:00to every member
Uptime report
Monday 14:00to every member

Pricing

Priced on events, not seats

Every plan includes the full issue pipeline - fingerprinting, stack traces, breadcrumbs and alerts. Paying moves the ceilings and unlocks the monitoring on top.

Free

For a single hobby project.

€0

forever

Start free
  • 1 project
  • 5,000 events / month
  • 7-day retention
  • 1 member
  • No monitors or source maps

Starter

For small teams shipping to production.

€4/mo

or €40 a year - two months free

Choose Starter
  • 3 projects
  • 50,000 events / month
  • 30-day retention
  • 3 members per project
  • 3 monitors - uptime or cron, plus a status page
  • 5 custom alert rules, 3 channels
  • Structured logs, source maps, spike detection

Business

For teams with volume, long retention and SSO needs.

€20/mo

or €200 a year - two months free

Choose Business
  • Unlimited projects and members
  • 2,500,000 events / month
  • 365-day retention
  • Unlimited monitors, alert rules and channels
  • Teams with SSO (OIDC)
  • Everything in Pro

Every paid plan starts with a 14-day Pro trial, no card required. Billing is handled by Paddle as merchant of record, so VAT and sales tax are included at checkout. Limits apply to the project owner - collaborators in a Pro project get Pro features on their own Free account. Full limits are in the plan reference.

Find out before your users tell you.

Create a project, copy the DSN, and ship the SDK in your next deploy.

npm install bugcatch-sdk